How blog posts here indicate their age, and how I had too much fun with it.
Because I’ve been writing this blog for so long, I often share links to very
old posts. Three years ago, I added a feature: if the post is more than five
years old, there’s a message next to the dateline indicating the age.
The age descriptions adjust automatically when the post is rendered. I had
fun implementing the human-style age descriptions: “nearly 12 years”, “more than
seven years”, “exactly nine years”, etc:
NUMBER_NAMES=dict(enumerate( "zero one two three four five six seven eight nine ten".split() ))
The complete message is then something like “This is more than 14 years
old. Be careful” because many posts are technical, and details might have
shifted. For example: Tricky locals().
But some posts never become stale: they are evergreen. So back then I also
added a way to mark blog posts as evergreen. The message would change to
“This is eight years old, but it’s still good.” I marked blog posts
evergreen one by one when I shared them and saw the needless “Be careful”
warning.
Today I took it one step further: I made the “but it’s still good”
message customizable on each post. For example:
One of the things I like about running this site is that it is all mine. I
can change the software however I like. I can build features like this that
truly don’t matter, but they make me smile. And that is always good.
A git hook is a script in the .git directory of a git repo on your machine.
They run during various git operations. The important detail to understand about
hooks is that they do not get installed locally when you clone a repo. A newly
cloned repo never has active hooks. Hooks have to be enabled after cloning,
usually by you.
The attack Frank saw was dangerous because it wasn’t a cloned repo: it was a
local checkout that had hooks installed then shared as a Dropbox folder. So
when it landed on Frank’s machine, the hooks were active without him realizing
it.
Git hooks are not apparent: they are meant to sit quietly until they run and
ideally to be unobtrusive even then. But this attack made me want to know what
hooks were in each of my git directories.
In zsh, you can define a function called chpwd, and it
will execute whenever the current directory changes. Using this feature, I could
create a script that lists the active hooks when I change into a git
directory:
git_show_hooks(){ localgit_dir=$(gitrev-parse--absolute-git-dir2>/dev/null) if[[-z$git_dir]];then _git_shown_hooks_dir= return fi localhooks_dir=$(gitrev-parse--git-pathhooks) hooks_dir=${hooks_dir:a} # Only announce once per repo, not for every cd inside it. if[[$hooks_dir==$_git_shown_hooks_dir]];then return fi _git_shown_hooks_dir=$hooks_dir
local-ahooks localhook setoptlocaloptionsnullglob forhookin$hooks_dir/*;do if[[-f$hook&&-x$hook&&$hook!=*.sample]];then hooks+=(${hook:t}) fi done if(($#hooks));then echo-e"\e[31mgit hooks:\e[0m $hooks (from $git_dir)" fi }
Now entering a git repo I get an announcement of active hooks, if any. It’s
very rare to see a hook other than pre-commit, but if any are there, they will
be reported. The message will only be shown the first time I cd into a repo to
keep the noise down.
Once I had this in place, there was another git hook consideration I could
address: it’s common to have a .pre-commit-config.yaml file in a repo, but it’s
easy to forget to enable the pre-commit hook that will actually use the file.
Many developers probably have cloned repos where they haven’t enabled the
pre-commit hook, so the desired checks aren’t running.
A second chpwd function can look for the configuration file and let you know
if you have the pre-commit hook enabled:
git_check_precommit(){ localtoplevel=$(gitrev-parse--show-toplevel2>/dev/null) if[[-z$toplevel]];then _git_shown_precommit_dir= return fi # Only announce once per repo, not for every cd inside it. if[[$toplevel==$_git_shown_precommit_dir]];then return fi _git_shown_precommit_dir=$toplevel
if[[!-f$toplevel/.pre-commit-config.yaml]];then return fi localhooks_dir=$(gitrev-parse--git-pathhooks) hooks_dir=${hooks_dir:a} localpc_tool= if[[-f$hooks_dir/pre-commit]];then ifgrep-q'File generated by prek:'$hooks_dir/pre-commit2>/dev/null;then pc_tool=prek elifgrep-q'File generated by pre-commit:'$hooks_dir/pre-commit2>/dev/null;then pc_tool=pre-commit fi fi if[[-n$pc_tool]];then echo"$pc_tool installed" else echo-e"\e[31mpre-commit:\e[0m not installed,"\ "run 'pre-commit install' or 'prek install'"\ "($toplevel/.pre-commit-config.yaml)" fi }
add-zsh-hookchpwdgit_check_precommit
One more step, just to be extra safe: zsh doesn’t run the chpwd function when
starting a new shell. So we run the functions explicitly to check our initial
directory:
# Run them once on shell startup to check our starting directory.
git_show_hooks
git_check_precommit
These shell functions are keeping me aware of the enabled git hooks. The
messages might appear too often, and I might stop noticing them after a while,
but I think this is much better than not knowing what’s going on. I haven’t seen
any attacks, but I found at least one of my projects where I forgot to install
pre-commit.
Watching discussions happening online, I see a frequent unfortunate tic I’ll
call the Expert Asterisk. A beginner is asking for help, and experts are
answering. Then in the spirit of completeness, an expert throws in a fact or
detail far from the learner’s abilities or needs.
As an example, here was an interaction about git: a new learner was having
trouble getting properly oriented. They were asking how branches relate to
directories, and how to undo a change. They knew about git init but
didn’t know how it related to changing projects.
newb: so every time I change project I simply do ‘git init’ on them?
expert1: ‘git init’ is for creating a new project.
expert2: you change your working directory, typically, when you change project
So far so good, but then:
expert2: or you specify the git repo directory with the -C switch, but
it’s more typing to do, so hardly anyone does that unless there’s a very good
reason
What!? Why mention this while explicitly pointing out no one does it? The
newb just barely understands how git works at all. Why introduce obscure
command-line options that “hardly anyone” uses?
I call this an asterisk because it feels like an esoteric footnote that only
experts, academics, or completionists would need to know.
The expert is trying to be helpful. They are presenting all the options in
the optimistic hope that the newb will be able to pick and choose among them.
Worse, sometimes multiple experts each offer their own asterisks, and the
poor newb is intrigued and distracted by each one. The new learner doesn’t have
a way to sift out which details might be important to them. Their original
question gets lost in the spreading tangents.
It’s hard to help new learners: we can’t know where their gaps are. What
misconceptions need to be unwound? Often we have only a glimpse of their
context. Experts can miss when they use words slightly wrong, taking them at
face value instead of seeing the misunderstanding that leads down the wrong
path.
Notice in the exchange above, “change project” could mean switching among
existing projects or starting a new project. We’re not sure which they meant. An
expert will cycle among a number of active projects, but beginners will work on
one until it is done, then switch to a new project, never returning to the
previous one. Perhaps “every time I change project I do ‘git init’” was right
for their situation.
The -C comment didn’t derail the session, but the effort of that
comment could have instead been used to clarify the newb’s need.
I understand why experts add these asterisks to help sessions: they are
useful for some people even if not for this beginner, and experts are interested
(even fascinated) by all the intricate details. These discussion areas are not
strictly for newb-help. They’re for general discussion among many people.
There’s no rule against talking about advanced or rare options.
And it’s hard to know what will be useful, or what the newb really means, or
what will resonate with them to help them find a solution. It’s all
difficult.
But you should at least recognize who you are addressing and whether you are
helping them. If you want to help the beginner, try to resist the impulse to add
little-traveled tangents. Focus on the question at hand and try hard to
understand the newb’s situation and mindset. Speak their language so they can
hear you.
This is a lightning talk I did at PyCon US 2026: Silence is Golden. The
overall message is to leave some quiet time so that reluctant speakers have a
chance to participate. I start with a jokey disclaimer because I followed Simon
Willison who gave an energetic, entertaining, and loud(!) speed-run through a
year of progress in LLMs:
I do these talks and blog posts about how to better interact with people, but
I hope they don’t come off as too preachy. I have to remind myself to keep these
ideas top of mind. I am one of those people who speak easily that I describe in
the lightning talk. I have to remember to hold back, to leave time and space for
other people.
I had the idea for this lightning talk a few years ago at PyCon, while
watching things going wrong. I was in a room with a few dozen people. The goal
in the room was to hear from lots of people, but the leader of the discussion
was a “speaks easily” kind of person, and I could see the dynamic of the room
failing to make space for everyone.
I was really pleased to be able to extend the time-tested and well-known
Pac-Man Rule from space to time. It made for an
interesting hook, making the talk more interesting than just a scold.
It’s really hard to keep quiet. But it’s important sometimes.
A tiny language, to explain how programming languages are implemented.
I wrote a tiny language implementation: Calcium.
It’s meant as a demonstration of how languages like Python are implemented. It
has a tokenizer, a parser, an AST, a compiler, bytecodes, and an execution
engine, all in about 300 lines of code.
I did it because I often see the question: isn’t Python interpreted? Why do
people say it’s compiled? (BTW, I also answered this in an earlier blog post:
Is Python interpreted or compiled? Yes.) It can be hard to explain
that your Python program never becomes an explicit sequence of native CPU
instructions, which is what people often think “compiled” means.
So I coded up Calcium to have on hand the next time
it comes up. I think it will help to be able to show the execution engine code
reading bytecodes and doing what they say.
It could also be an interesting starting point for people wanting to play
with a language implementation. It has almost nothing, so there’s lots of
simple things (comments?) to add.
An idea for a new feature for coverage measurement: per-caller coverage
I’ve had an idea rattling around to get more detail from coverage
measurement. Can we measure the coverage in a function separately for each
caller of the function?
Here’s why I want it: in Acidica, my toy
BASIC interpreter, I had code to implement the built-in functions that looked
something like this:
matchfunc_name:
case"LEN": iflen(args)!=1: raiseTypeError(f"Wrong arguments for LEN, got {len(args)}") returnlen(args[0])
case"LEFT$": iflen(args)!=2: raiseTypeError(f"Wrong arguments for LEFT$, got {len(args)}") returnargs[0][:args[1]]
# ... 19 other built-ins ...
I didn’t like the repeated code here: each different func_name has to
check that it got its expected number of arguments and perhaps raise an error.
So I refactored:
defexpects(nargs:int,func_name:str,args:tuple)->None: iflen(args)!=nargs: raiseTypeError(f"Wrong arguments for {func_name}, got {len(args)}")
Nice. The code is tighter, easier to read, and common behavior is implemented
in one place.
But the old code had an advantage: because each error condition had its own
raise line, coverage measurement could tell me whether I had tested every
func_name for the wrong number of arguments. With the error handling
happening in a helper function, that information is lost. I’ll know that
somefunc_name had a test for the wrong number of arguments, but
not that all of them did.
Here’s where the new idea comes in. What if I could indicate that for the
expects function, I want separate coverage data for each distinct calling
site? Then I could see that every func_name had a test for both the wrong
number of arguments and the right number of arguments. The simple branch inside
expects would be measured separately for each caller.
I have a quick proof-of-concept. A decorator on expects does the work.
Coverage.py already has dynamic contexts which are used for things like tracking
which tests called which code. The decorator starts a new context named for the
calling location, then restores the context when the function returns:
I had to make one tiny (unreleased) change to coverage.py for this:
switch_context used to return None, but now it returns the previous
context so that we can nest them properly.
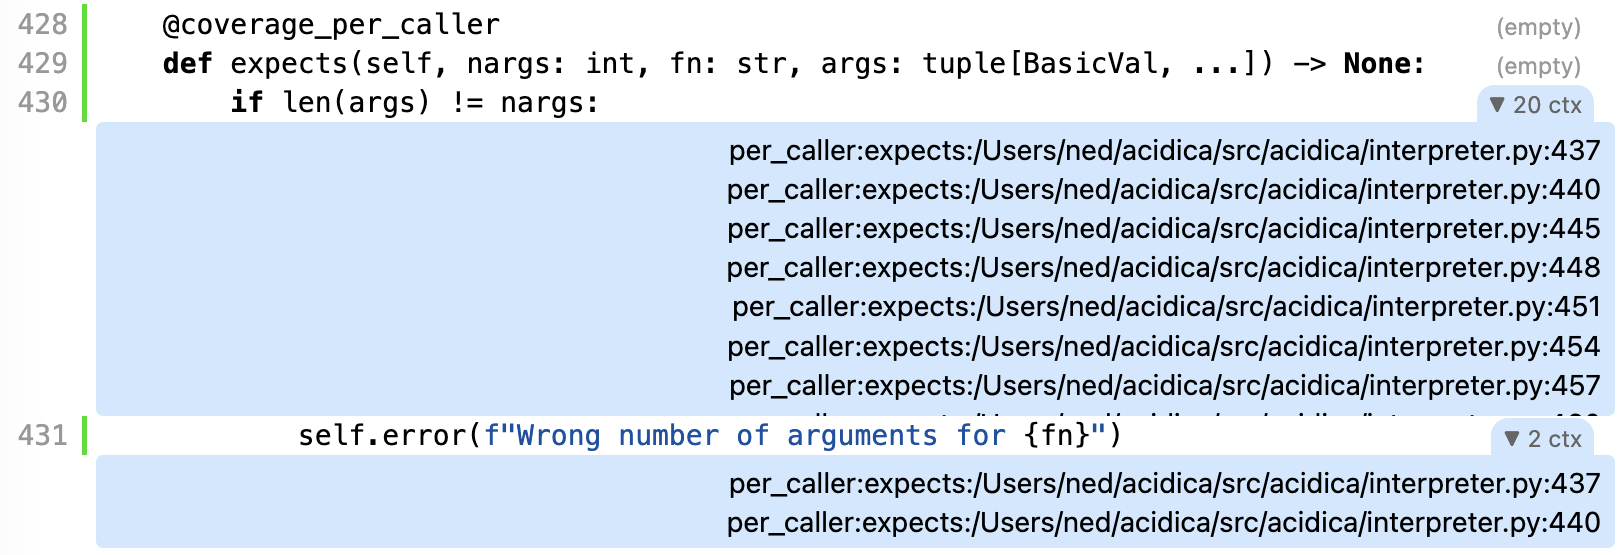
To my delight, this works! I can look at the HTML coverage report and see the
caller contexts for the lines in expects. I can see that 20 callers ran
the if line, but only 2 ran the raise, and the context names show
the file and line number of the callers for each:
This isn’t the whole solution yet. Things to improve:
I’d like to post-process these contexts to show which callers were missing
lines inside expects. What I’m looking for is the same kind of “this
line is missing” information that I got from the original inlined logic.
These per-caller contexts overwrite the contexts we were already collecting
(the test names). Ideally we’d have some kind of sub-context so that we could
track both (or many) at once.
It’s not great that I had to add a decorator to the source code. Driving
this through the coverage configuration would keep these kinds of details out of
the source.
But it’s a start, and gives me other ideas. I could use some aspect of the
data passed into a function as the context name. In this example, we could have
used func_name as the context instead of the caller’s location. Maybe
you have ideas for other uses.